Home / Articles / Re-anchoring: keeping an agent's rules alive through every summary, and a canary that shows when they are not
Re-anchoring: keeping an agent's rules alive through every summary, and a canary that shows when they are not
By Dinis Cruz · 2026-10-10 · article v1.1.0, 2 versions · sgit.ai v0.7.22 · agentsclaude-codehooksagent-behaviour-policycompactioncontextre-anchoringguardrailsgovernancearticle
Abstract: Instructions given only in conversation can be lost when a long session is summarised. The session that runs this site has been summarised eighteen times in a month, each time keeping under 2% of what it replaced. Re-anchoring is the answer: keep the agent's rules in a behaviour policy file and have the harness print it back after every summary, so the rules are restored rather than remembered. And because you cannot see what a summary drops, add a canary: a short status report, computed from the transcript, that ends every few answers. If it stops appearing, something in the policy has not been read. Both are running in this session now. This is how they work, what each piece is for, and why the best way to do it today is a recipe that someone has to keep up to date.
Five readerstwo minutes · the arc · 9 slides · a map · 116 catalogued items, 6 flagged
This article read again, after it was written, by five of the desk's readers: the Explainer, the Historian, the Storyteller, the Cartographer and the Librarian. None adds a claim the article does not make. Read from article v1.0.0 on 10 October 2026; the views are not part of the article's text and do not change its version. How the five readers work.
In two minutes (Explainer): Stopping an AI assistant forgetting its rules
The point. When a long AI conversation fills up, the software swaps it for a short summary the AI writes, and a rule given only in conversation can vanish unnoticed. The article's fix, re-anchoring, keeps the rules in a file that the software pastes back after every summary, so they are restored, not remembered. A short status report every few answers is a warning light: if it stops appearing, something was not read.
An example. The session behind the author's site was summarised eighteen times in a month, each time keeping on average 1.7% of what it replaced. Its report measures one rule, "leak scan before every commit" (check for secrets before saving work). Rather than asking the AI, it counts saves with no scan before them. That number should be zero.
Why it matters to you. Re-anchoring keeps rules in view but does not enforce them; an AI can still miss its own mistake or argue itself into an exception. The right set-up also changes with each software release.
If you remember one thing. Keep the rules in a file that comes back after every summary, and watch for the report that shows it did.
Words used.
- Compaction: the software summarising a long conversation to make room.
- Hook: a step the software runs automatically, such as after every summary.
- Canary: a regular signal whose absence warns you something is wrong.
In the arc (Historian): What it added, and where it sits
Introduced.
- The canary: a status report computed from the transcript, checked by a
Stophook and expected by the person, so a missing report signals that the policy was not read (canary). - The name re-anchoring, for what article 4 called "a reminder": a hook on the
compactmatcher that prints the policy back after every summary. - One policy file with three jobs: memory, the checker's rulebook, the enforcement list.
- A policy row as "a rule, its barrier, and the current recipe for keeping it", and the maintained recipe library as the thing people will pay for.
The nugget. "The rules are restored, not remembered." It names the move the whole set has been making: a rule taken out of the model's memory and put back by something outside it.
Reused. Almost everything. From a-second-reader-the-agent-cannot-skip, its only link: the three failure modes, voice-incident, compaction-warning, placement, hook, recipe, re-anchoring. From every-mistake-added-a-rule (not linked): compaction, forgetting, memory-as-files, record-reading. From article 1: the barrier kinds and enforcement-audit, now as one measured rule (commits not preceded by a leak scan). Before the set, memory-is-not-a-spectator-sport described the same session summarised across resets.
Changed. It extends article 1's policy row from rule and barrier to rule, barrier and recipe, and is explicit that re-anchoring "does not change a rule's barrier". Article 4 ranked the fixes by strength; this one ranks them by order: re-anchoring "is the first and cheapest of the three, and the others depend on it".
Left open.
- "The re-anchor after a compaction has not been observed yet."
- The canary is a setting, not a boundary, and a report can be pasted without the rules being followed.
- Who keeps the recipe library current across platforms and versions.
- Librarian flags: the 17.8 million token total does not reconcile with eighteen compactions of about 790,000; "the most important one I have read this week" is a superlative; the three failures are named only in a caption.
Contribution. 1 new / 26 total. The lowest ratio in the set, and accurate: this article is assembly, putting article 4's taxonomy and article 2's file memory into a running configuration, with the canary as its one new part.
In pictures (Storyteller): 9 slides
Swipe or scroll sideways. Download the deck as a PDF (one page per slide, ready for a LinkedIn document post).
On the map (Cartographer): The argument as a map: how the rules survive every summary, and how the person sees that they have.
The catalogue (Librarian): 116 items, each anchored to a sentence of the article
Everything the article contains, by kind. Every item was extracted with the exact sentence it came from, and a script checked each one against the article.
Claims: 26
- Instructions given only in conversation can be lost when a long session is summarised (lead)
- Anthropic's own permission classifier has the same weakness as conversation-only instructions (lead)
- The documentation sentence is the most important the author read that week about running agents, because it explains a failure just witnessed (lead)
- Summaries are frequent, heavy and invisible (In short)
- A rule held only in conversation has to win every summary; when it does not, nothing tells you (In short)
- Re-anchoring takes the rule out of the contest: rules are restored, not remembered (In short)
- Re-anchoring fixes forgetting, not the other two failures; those need a second reader and a gate (In short)
- A canary makes the invisible visible: if the report stops appearing the person notices before anything important goes wrong (In short)
- The best recipe changes with every release; keeping it current per rule, platform and version is continuous work (In short)
- Summaries are not criticised: they make a month-long session possible, and the site would not exist in its current form without them (What summarisation does to a session)
- At every summary a conversational rule must be judged important enough to keep, in words the summariser chooses; you are not told when it fails (What summarisation does to a session)
- The platform already has a pattern: what comes back from disk survives; what lived only in conversation competes (What summarisation does to a session)
- A rule held by the agent it governs can fail in three different ways that need different fixes (Three ways a rule fails)
- Re-anchoring is the first and cheapest of the three fixes, and the others depend on it (Three ways a rule fails)
- The SessionStart compact hook is the heart of re-anchoring: point it at the policy file and the policy is back verbatim when the summary is done (Re-anchoring: the rules come back from disk)
- The point of the hooks is that neither alternative depends on someone remembering (Re-anchoring: the rules come back from disk)
- Here the Agent Behaviour Policy stops being a document and becomes infrastructure: one file does three jobs (One file, three jobs)
- Job 1, memory: the file is what the re-anchoring hook prints back; rules survive because they live on disk (One file, three jobs)
- Job 2, the checker's rulebook: the draft guard's numbered rule file, written by the inbox agent, is already an ABP fragment (One file, three jobs)
- Job 3, the enforcement list: every row carries its barrier, so the file says which rules still need a second reader or gate (One file, three jobs)
- Such a row is still an expectation but a checkable one: a hook can see whether the file was written (One file, three jobs)
- The show-the-report rule moves from expectation to setting (The canary: a report that ends every few answers)
- A policy row with a number next to it is different from a policy row on its own (The canary: a report that ends every few answers)
- The compact matcher makes re-anchoring a five-line hook rather than a workaround (The recipe changes with the platform)
- Six months ago the best re-anchoring recipe was different, and will be again in six months; on another platform it is different today (The recipe changes with the platform)
- The recipe table goes out of date with every release; keeping it current, testing it and costing it is real continuous work (The recipe changes with the platform)
Evidence: 7
- Claude Code documentation: an instruction that disappeared after compaction was given only in conversation, sits in a nested CLAUDE.md not yet reloaded, or is an unmatched path-scoped rule (lead)
- Permission modes documentation: a boundary can be lost if compaction removes the message that stated it (lead)
- Documentation: project-root CLAUDE.md survives compaction and is re-read from disk and re-injected after /compact (What summarisation does to a session)
- Documentation: invoked skills are re-injected but capped at 5,000 tokens per skill and 25,000 total, oldest dropped first (What summarisation does to a session)
- Documentation: context added earlier by hooks is summarised with the rest of the conversation (What summarisation does to a session)
- Snopes and NPR both report the clause was a quick check that the venue had read the whole contract (The canary: a report that ends every few answers)
- Documentation: edits to hooks in settings files are normally picked up automatically by the file watcher (Living with it)
Data points: 8
- Each compaction turned about 785,000 tokens into 9,000 to 19,000 (figure caption) (lead)
- About 98% of the context replaced by a model-written summary each time (In short)
- Eighteen compactions between 9 September and 9 October, all automatic (What summarisation does to a session)
- Each compaction started from about 780,000 to 800,000 tokens and kept 9,000 to 19,000; on average 1.7% kept (What summarisation does to a session)
- 17.8 million tokens of conversation summarised away in total (What summarisation does to a session)
- Each summary took 1.2 to 3.4 minutes to write (What summarisation does to a session)
- The first report rendered on a phone at 41 characters wide without wrapping (Living with it)
- The report is shown every three answers today (Living with it)
Facts: 22
- The hooks re-anchoring depends on arrived or changed in the last few months (In short)
- When the context fills, the harness writes a summary of the conversation and continues from the summary (What summarisation does to a session)
- Claude Code has four documented hook places to do re-anchoring (Re-anchoring: the rules come back from disk)
- SessionStart with matcher compact fires after every compaction and can print the whole policy back; its plain-text stdout is added to context (Re-anchoring: the rules come back from disk)
- UserPromptSubmit fires before each prompt, including harness-started turns, and can add a short anchor every turn or the full policy every Nth turn as additionalContext (Re-anchoring: the rules come back from disk)
- PreCompact fires before compaction and can log it or block it (Re-anchoring: the rules come back from disk)
- Stop fires when the agent is about to end its turn and can check a required thing happened, sending the agent back once (Re-anchoring: the rules come back from disk)
- The reanchor step prints a one-line header naming policy v0.1 #a0d6d2, then the policy, and logs that it ran (Re-anchoring: the rules come back from disk)
- The prompt step adds one line to every prompt naming the policy, its version and hash (Re-anchoring: the rules come back from disk)
- Report line policy: version, hash and rule count; a surprise means the file changed or another is loaded (The canary: a report that ends every few answers)
- Report line anchor: re-anchors against compactions; fewer re-anchors than compactions means the hook did not fire (The canary: a report that ends every few answers)
- Report line cost: session cost and change since last report; a surprise means a long silent task or a loop (The canary: a report that ends every few answers)
- Report line tokens: output and cached tokens (The canary: a report that ends every few answers)
- Report line web: searches and fetches; a surprise means research not asked for or not seen (The canary: a report that ends every few answers)
- Report line tools: tool calls and background agents (The canary: a report that ends every few answers)
- Report line commits: commits since the policy started and how many lacked a preceding leak scan; should be zero (The canary: a report that ends every few answers)
- Rule 2 of this session's policy is leak scan before every commit (The canary: a report that ends every few answers)
- Mods, the event system the draft guard used, arrived in Claude Code v2.1.287 (The recipe changes with the platform)
- onFailure: "block", making a settings hook fail closed, arrived in v2.1.295 (The recipe changes with the platform)
- Prompt hooks changed how they deny in v2.1.210 (The recipe changes with the platform)
- Written from a conversation between Dinis Cruz and agent@riskmandate.ai (Claude Opus 5.5) in the sgit.ai site session, which built and runs under the hooks, on 9 and 10 October 2026 (footer)
- Claude Code behaviour is quoted from its documentation as read on 9 October 2026; compaction figures are from the session transcript (footer)
Hypotheses: 1
- A maintained, version-aware library of recipes is what people will pay for, not the policy itself (The recipe changes with the platform)
Open questions: 2
- The re-anchor after a compaction has not been observed yet; the article will be updated when it is (Living with it)
- Open: how often to show the report (every three answers today), which lines people read, and what else belongs (Living with it)
Definitions: 5
- Re-anchoring: the technique the author has started calling by that name, for the general problem of rules lost at summaries (lead)
- Compaction: in Claude Code, the harness writes a summary of the conversation when context fills and continues from it; manual or automatic (What summarisation does to a session)
- Expectation (ABP vocabulary): a rule in prose, enforced by nobody (Three ways a rule fails)
- Canary: a short status report at the end of every few answers, the second half of the technique (The canary: a report that ends every few answers)
- A behaviour policy row is a rule, its barrier, and the current recipe for keeping it (The recipe changes with the platform)
Methods: 10
- Cheapest version, no hooks: a line in project-root CLAUDE.md saying to read the behaviour policy, since that file is re-read after compaction (Re-anchoring: the rules come back from disk)
- Bluntest version, no configuration: the person types 'read your instructions again' (Re-anchoring: the rules come back from disk)
- A policy can shape memory directly with rows like keep decisions in decisions.md, moving important parts of a session into files (One file, three jobs)
- The report reads the transcript and counts commits not preceded by a scan instead of asking the agent (The canary: a report that ends every few answers)
- Step 1: write the rules as an ABP file, short enough to re-read (a few hundred words), each rule with its barrier (Build your own)
- Step 2: re-anchor after every compaction with a SessionStart compact hook printing the file, plus a one-line anchor on every prompt (Build your own)
- Step 3: add a canary report every few answers, computed from the transcript, with a Stop hook checking it was shown (Build your own)
- Step 4: give the person two commands, show status and reload the policy (Build your own)
- Step 5: measure one rule in the report so the canary is also evidence (Build your own)
- Step 6: move the rules that matter most from expectation to a reader or a gate, using the file as the list (Build your own)
Decisions: 4
- The model does not write the numbers: the UserPromptSubmit hook computes the report from the transcript and cost record, because a model-written report would need verifying (The canary: a report that ends every few answers)
- The harness checks the report was shown: the Stop hook sends the agent back once if missing, then lets the turn end and logs the miss (The canary: a report that ends every few answers)
- The person is part of the loop, with /abp-status to show the report and /abp-reload to re-read the policy and state version and hash (The canary: a report that ends every few answers)
- This session's report runs on settings hooks rather than a mod, because of the cost of running unsandboxed mod code (The recipe changes with the platform)
Limitations: 8
- Re-anchoring does not change a rule's barrier; an expectation stays a rule in prose enforced by nobody, but reliably in view (Three ways a rule fails)
- Re-anchoring cannot be seen working: a silent hook, unloaded settings or moved policy look like a healthy session (The canary: a report that ends every few answers)
- The cost line can lag because the harness cost record is written periodically (Living with it)
- A recipe using mods means running agent-written code unsandboxed with your permissions, itself a policy row (The recipe changes with the platform)
- Re-anchoring does not enforce anything; a rule in view is still an expectation (What it does not do)
- The canary is a setting, not a boundary: it lives in a settings file the session could edit and cannot stop an agent ignoring the policy (What it does not do)
- A report can be pasted without the rules being followed; for the rest you need a reader or a gate (What it does not do)
- Summaries stay a black box; re-anchoring makes what matters independent of them (What it does not do)
Examples: 3
- On 9 October two emails drafted by an agent went out in the author's voice against a rule written down four times; one reason was the rule fell out of context at a summary (lead)
- Van Halen's touring contract asked for M&M's with the brown ones removed, to tell whether the venue read the whole contract including safety parts (The canary: a report that ends every few answers)
- The hooks loaded mid-session: added to a user settings file while running, and the next prompt carried the one-line anchor (Living with it)
Sources: 8
- Earlier article on the fix for the email incident: a second reader the agent cannot skip (lead)
- Snopes fact-check on the brown M&M's (The canary: a report that ends every few answers)
- NPR, The truth about Van Halen and those brown M&M's (The canary: a report that ends every few answers)
- Claude Code docs: memory (lead)
- Claude Code docs: permission modes (lead)
- Claude Code docs: context window, what survives compaction (What summarisation does to a session)
- Claude Code docs: hooks (Re-anchoring: the rules come back from disk)
- Agent Behaviour Policy site, abp.sgit.ai (Three ways a rule fails)
Artefacts: 7
- Figure ra-compactions.webp: every compaction in this session, read from its transcript (lead)
- Figure ra-failures.webp: re-anchoring fixes forgetting, a second reader fixes the unseen violation, a gate fixes the argued exception (Three ways a rule fails)
- The settings hooks configuration running in this session: SessionStart (compact), UserPromptSubmit and Stop, each calling abp.py (Re-anchoring: the rules come back from disk)
- abp.py at ~/.claude/abp/, with reanchor, prompt and stop steps (Re-anchoring: the rules come back from disk)
- Figure ra-phone.webp: the report on a phone in this session on its first day (The canary: a report that ends every few answers)
- Figure ra-loop.webp with Mermaid source: one policy file, three hooks, two commands, and a person (The canary: a report that ends every few answers)
- Figure ra-card.webp: branded card version of the report, rendered on request, footer says what to do if it stops appearing (The canary: a report that ends every few answers)
Names: 5
- Agent Behaviour Policy (ABP), with its own site abp.sgit.ai (Three ways a rule fails)
- Van Halen (The canary: a report that ends every few answers)
- Claude Code (Anthropic) (lead)
- Dinis Cruz, author (footer)
- Claude Opus 5.5 (claude-opus-5-5), the agent agent@riskmandate.ai (footer)
Flagged for the author: 6
- Total does not reconcile with per-compaction figures: eighteen compactions of about 780,000 to 800,000 tokens give about 14.1 to 14.4 million, but the article says "In total, 17.8 million tokens of conversation have been summarised away." (about 989,000 per compaction).
- "one of the reasons was that the rule fell out of the agent's context when the conversation was summarised" and "a rule that had been written down four times" are asserted without evidence in this article; support lives in the linked a-second-reader article.
- Superlative in the author's voice: "That sentence is the most important one I have read this week about running agents" (house style says no superlatives).
- "The hooks this depends on arrived or changed in the last few months." Only mods (v2.1.287), onFailure (v2.1.295) and prompt-hook deny (v2.1.210) are versioned, with no dates; the compact matcher and SessionStart are not dated, so "last few months" is unsupported here.
- Graph gaps: sources/re-anchoring-agent-behaviour-policies.graph.json links omit sources cited in the article: permission-modes docs, NPR and abp.sgit.ai.
- Section 'Three ways a rule fails' names the three failures only in the figure caption ("Re-anchoring fixes forgetting. A second reader fixes the violation the author cannot see. A gate fixes the exception the agent argues itself into."); the prose never lists them, so the content depends on the image directive.
The five readers have also read:
- Zoom into an agent's behaviour policy and you find the business logic
- Every mistake added a rule
- Hope or enforcement
- A second reader the agent cannot skip
Every view, the role files and the tools are in the Article Views vault.
Claude Code's documentation says it plainly: "If an instruction disappeared after compaction, it was given only in conversation, lives in a nested CLAUDE.md that hasn't reloaded yet, or is a path-scoped rule that hasn't matched a file since" (memory). Anthropic's own permission classifier has the same weakness, in its own words: a boundary "can be lost if context compaction removes the message that stated it" (permission modes).
That sentence is the most important one I have read this week about running agents, because it explains a failure I had just watched happen. On 9 October two emails drafted by one of my agents went out in my voice, against a rule that had been written down four times; one of the reasons was that the rule fell out of the agent's context when the conversation was summarised. I wrote about the fix for that email, a second reader the agent cannot skip. This article is about the general problem underneath it, and a technique for it that I have started calling re-anchoring.
In short
- Summaries are frequent, heavy and invisible. This session has been summarised eighteen times in a month. Each time about 98% of the context was replaced by a summary written by the model, and nothing told me what was kept.
- A rule held only in conversation has to win every summary. It often will. When it does not, nothing tells you.
- Re-anchoring takes the rule out of that contest. The rules live in a file, an Agent Behaviour Policy, and a hook prints the file back into the context after every summary, verbatim. The rules are restored, not remembered.
- Re-anchoring fixes forgetting, not the other two failures. An agent that has its rules in view can still miss its own violation or argue itself into an exception. Those need a second reader and a gate.
- A canary makes the invisible visible. A short report, computed from the transcript, ends every few answers. If it stops appearing, the person notices before anything important goes wrong: the brown M&M.
- The best recipe changes with every release. The hooks this depends on arrived or changed in the last few months. Keeping the recipe current for each rule, on each platform, at each version, is work someone has to do continuously.
What summarisation does to a session
Long agent sessions do not keep everything. When the context fills, the harness writes a summary of the conversation so far and continues from the summary. In Claude Code this is compaction, and it can be manual or automatic.
The transcript of this session records every one. Between 9 September and 9 October there were eighteen compactions, all automatic. Each started from about 780,000 to 800,000 tokens of context and replaced it with 9,000 to 19,000: on average 1.7% kept. In total, 17.8 million tokens of conversation have been summarised away. Each summary took between 1.2 and 3.4 minutes to write.
None of that is a criticism. A summary is what makes a month-long session possible at all, and this site would not exist in its current form without it. But it changes what a rule given in conversation is. Every time a summary is written, the rule has to be judged important enough to keep, in words the summariser chooses. Often that works. You are not told when it does not.
The documentation is precise about what does survive: "Project-root CLAUDE.md survives compaction: after /compact, Claude re-reads it from disk and re-injects it into the session" (memory). Skills that were invoked are re-injected too, but "capped at 5,000 tokens per skill and 25,000 tokens total; oldest dropped first", and context that hooks added earlier is "summarized with the rest of the conversation" (context window). So there is already a pattern in the platform: what comes back from disk survives; what lived only in the conversation competes.
Three ways a rule fails
A rule held by the agent it governs can fail in three different ways, and they need different fixes:
Re-anchoring is the first and cheapest of the three, and the others depend on it: a checker that reads the rules, and a gate that enforces them, are only as good as the rules they are given. In the vocabulary of the Agent Behaviour Policy, re-anchoring does not change a rule's barrier. An expectation stays "a rule in prose, enforced by nobody". What changes is that the expectation is reliably in view, which is the precondition for everything else.
Re-anchoring: the rules come back from disk
Claude Code has four documented places to do it (hooks):
| Hook | When it fires | What it can do for the policy |
|---|---|---|
SessionStart, matcher compact | after every compaction, automatic or manual | print the whole policy back: "Claude Code adds a SessionStart hook's plain-text stdout to Claude's context" |
UserPromptSubmit | before each prompt is processed, including turns the harness starts itself | add a short anchor every turn, or the full policy every Nth turn, as additionalContext |
PreCompact | before compaction | log that it is about to happen, or block it |
Stop | when the agent is about to end its turn | check that something the policy requires actually happened, and if not, send the agent back once |
The first is the heart of it. A hook with the compact matcher fires "after compaction", and whatever it prints goes back into the context. Point it at the policy file and the policy is back, verbatim, the moment the summary is done. This is the configuration running in this session:
{
  "hooks": {
    "SessionStart": [
      { "matcher": "compact",
        "hooks": [ { "type": "command", "command": "python3 ~/.claude/abp/abp.py reanchor" } ] } ],
    "UserPromptSubmit": [
      { "hooks": [ { "type": "command", "command": "python3 ~/.claude/abp/abp.py prompt" } ] } ],
    "Stop": [
      { "hooks": [ { "type": "command", "command": "python3 ~/.claude/abp/abp.py stop" } ] } ]
  }
}
The reanchor step prints a one-line header, "ABP re-anchored after compaction: v0.1 #a0d6d2. The rules below still apply, whatever the summary says", then the policy, and logs that it ran. The prompt step adds one line to every prompt, naming the policy, its version and its hash, so even a turn that starts from a thin summary knows the policy exists and where it lives.
The cheapest version needs no hooks at all: a line in the project-root CLAUDE.md that says "read the behaviour policy in this file before acting", since that file is re-read from disk after compaction. And the bluntest version needs no configuration: the person types "read your instructions again". Both work. The point of the hooks is that neither depends on someone remembering.
One file, three jobs
This is where the Agent Behaviour Policy stops being a document and becomes infrastructure. The same file does three jobs:
- Memory. It is what the re-anchoring hook prints back. The rules survive because they live on disk, not in the conversation.
- The checker's rulebook. It is what an independent checker reads. The draft guard's numbered rule file, written by the inbox agent, is already an ABP fragment under another name.
- The enforcement list. Every row carries its barrier, so the file says which rules are still expectations, and therefore which need a second reader or a gate next.
A policy can also shape memory directly. A row can say "keep decisions in decisions.md" or "write the sources file before drafting", which moves the important parts of a session out of the conversation, where they are summarised, and into files, where they are not. That is still an expectation, but a checkable one: a hook can see whether the file was written.
The canary: a report that ends every few answers
Re-anchoring has a weakness of its own: you cannot see it working. A hook that silently stopped firing, a settings file that was not loaded, a policy file that was moved, all look exactly like a session where everything is fine. So the second half of the technique is a canary.
The idea is old. Van Halen's touring contract had a clause, in the middle of pages of technical requirements, asking for a bowl of M&M's with the brown ones removed. It was not vanity. As Snopes and NPR both report, it was a quick way to tell whether the venue had read the whole contract, including the parts about weight and power that kept the crew safe. Brown M&M's in the bowl meant: check everything else.
The agent version is a short status report at the end of every few answers. Here is how it looks on a phone, in this session, on its first day:
Three design choices make it more than decoration:
- The model does not write the numbers. The
UserPromptSubmithook computes the report from the session transcript and the harness's own cost record, and hands it to the agent with the instruction to paste it. A report the model wrote from memory would be one more thing to verify. - The harness checks it was shown. When a report was due, the
Stophook reads the end of the answer. If the report is missing it sends the agent back, once, with the block to add; if it is still missing, it lets the turn end and logs the miss. That one rule, show the report, moves from expectation to setting. - The person is part of the loop. After a few days the report is expected. When it does not arrive, the question is "where is my report?", and the answers are two commands:
/abp-statusshows it now, and/abp-reloadmakes the agent read the policy again and say its version and hash.
Re-anchoring and the canary, Mermaid source
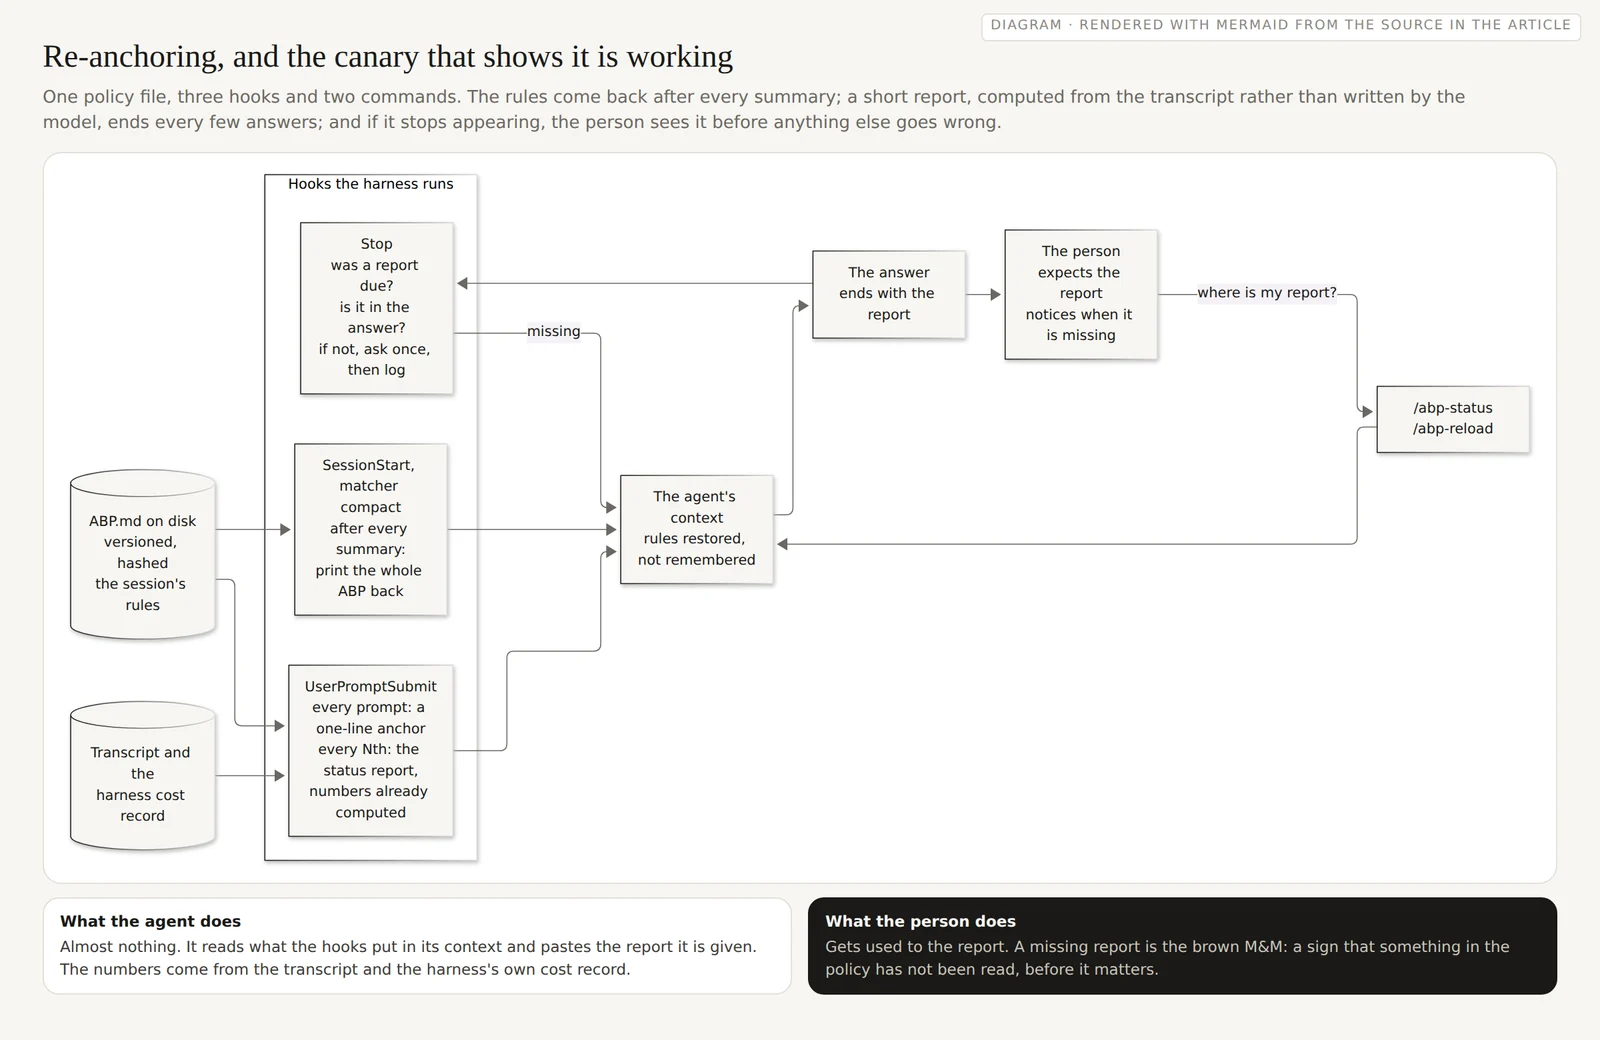
flowchart LR
  ABP[("ABP.md on disk<br/>versioned, hashed<br/>the session's rules")]
  subgraph H["Hooks the harness runs"]
    direction TB
    SS["SessionStart, matcher compact<br/>after every summary:<br/>print the whole ABP back"]
    UP["UserPromptSubmit<br/>every prompt: a one-line anchor<br/>every Nth: the status report,<br/>numbers already computed"]
    ST["Stop<br/>was a report due?<br/>is it in the answer?<br/>if not, ask once, then log"]
  end
  CTX["The agent's context<br/>rules restored, not remembered"]
  ANS["The answer<br/>ends with the report"]
  U["The person<br/>expects the report<br/>notices when it is missing"]
  CMD["/abp-status<br/>/abp-reload"]
  TR[("Transcript and the<br/>harness cost record")]
  ABP --> SS --> CTX
  ABP --> UP --> CTX
  TR --> UP
  CTX --> ANS --> ST
  ST -- "missing" --> CTX
  ANS --> U
  U -- "where is my report?" --> CMD --> CTX
Each line in the report earns its place:
| Line | What it tells you | What a surprise would mean |
|---|---|---|
| policy | the version and hash in force, and how many rules | the file changed, or a different one is loaded |
| anchor | re-anchors against compactions since the policy started | fewer re-anchors than compactions: the hook did not fire |
| cost | the session's cost, and the change since the last report | a long silent task, or a loop |
| tokens | output and cached tokens | how much context work the session is doing |
| web | searches and fetches | research happening that you did not ask for, or did not see |
| tools | tool calls and background agents | the shape of the work since the last report |
| commits | commits since the policy started, and how many were not preceded by a leak scan | a rule measured, not asserted: that number should be zero |
The last line is the one I like most. Rule 2 of this session's policy is "leak scan before every commit". The report does not ask the agent whether it complied; it reads the transcript and counts commits that were not preceded by a scan. A policy row with a number next to it is a different thing from a policy row on its own.
There is also a branded version, rendered as an image on request, for when the report is shown to someone else:
Living with it
The first observations, honestly, after one evening:
- The hooks loaded mid-session. They were added to a user settings file while the session was running, and the next prompt arrived carrying the policy's one-line anchor. The documentation says edits to hooks in settings files are "normally picked up automatically by the file watcher", and that is what happened here.
- The first report rendered on a phone at 41 characters wide without wrapping.
- The re-anchor after a compaction has now been observed. Updated 10 October 2026: at 12:03:36 UTC the session was summarised for the nineteenth time, automatically, from 789,144 tokens to 12,092. The
SessionStarthook fired in the same second, printed the policy back from disk, and logged the event; the session resumed with the full policy in view, and theanchorline moved to 1 re-anchor for 1 compaction. The release that followed ran its leak scan before the commit, as rule 2 asks. - Then the canary did its other job. At about 15:16 UTC the session's container was restarted, and everything outside the repository and the transcript went with it: the policy file, the script and the hooks in the user settings. The next prompt arrived with no anchor line. What the agent noticed first was its missing working files; the absent anchor confirmed that the hooks had gone too, and the first report due after the restart would have been missing, which is the signal the person watches for. The policy was restored from the copy the last re-anchor had printed into the conversation, and its hash came back as the same
#a0d6d2, byte for byte. The script was rebuilt, carrying the last report's totals as a baseline. Lesson: a policy that lives on an ephemeral machine needs a copy somewhere that survives it, and the anchor line is worth keeping even when no report is due. - The leak scan counter was undercounting scans. It recognised one way of writing the scan, so commits that were scanned in a different way were counted as unscanned. The scan is now one script that every commit runs, and the counter looks for that script.
- The cost line can lag. It comes from the harness's cost record, which is written periodically rather than after every call.
We are going to live with it for a while: how often to show it (every three answers today), which lines people actually read, and what else belongs there. That is the point of running it in the session that writes about it.
The recipe changes with the platform
Everything above depends on features that are recent. Mods, the event system the draft guard used, arrived in Claude Code v2.1.287. onFailure: "block", which makes a settings hook fail closed, arrived in v2.1.295. Prompt hooks changed how they deny in v2.1.210. The compact matcher is what makes re-anchoring a five-line hook rather than a workaround. Six months ago the best way to re-anchor a policy was different, and six months from now it will be different again; on another platform it is different today.
So a behaviour policy row is not only a rule and its barrier. It is a rule, its barrier, and the current recipe for keeping it: on this platform, at this version, use these hooks, placed here, and expect this barrier. That table goes out of date with every release, and keeping it current, testing it, and noting what each recipe costs is real, continuous work. Some recipes carry costs of their own: a recipe that uses mods means running code the agent wrote, unsandboxed, with your permissions, which is itself a row in the policy. That is why this session's report runs on settings hooks rather than a mod.
That maintained, version-aware library of recipes is what I think people will pay for: not the policy, which they can write, but the current best way to make each row hold, curated for the tools they actually use.
What it does not do
- Re-anchoring does not enforce anything. It keeps rules in view. A rule in view is still an expectation.
- The canary is a setting, not a boundary. It lives in a settings file the session could edit. It tells you the policy is being read; it cannot stop an agent that decides to ignore it.
- A report can be pasted without the rules being followed. It shows that the hooks fired and the policy was loaded, and it measures what can be measured from the transcript. For the rest you need a reader or a gate.
- The summaries stay a black box. Re-anchoring does not show what a summary kept. It makes what matters independent of it.
Build your own
- Write the rules down as an ABP file, short enough to re-read (a few hundred words), each rule with its barrier.
- Re-anchor after every compaction with a
SessionStarthook on thecompactmatcher that prints the file, and a one-line anchor on every prompt. - Add a canary: a short report every few answers, computed from the transcript, with a
Stophook that checks it was shown. - Give the person two commands: show the status, and reload the policy.
- Measure one rule in the report, so the canary is also evidence.
- Move the rules that matter most from expectation to a reader or a gate, using the file as the list.
Written from a conversation between Dinis Cruz and agent@riskmandate.ai (Claude Opus 5.5, claude-opus-5-5) in the sgit.ai site session, which built and installed the re-anchoring hooks and the status report described here, on 9 and 10 October 2026, and runs under them. Compaction figures are from this session's own transcript. Claude Code behaviour is quoted from its documentation as read on 9 October 2026.
Threads
Builds on
- A second reader the agent cannot skip: how two wrong emails became a gate on every draft Two emails went out in my voice despite a written rule. The fix: a hook that makes a second model approve every draft, failing closed.
Continued by
- The infographic bake-off: which image model for which job, judged blind on 10 October 2026 Every image model on OpenRouter, eleven briefs, 101 images judged blind, $10.44: which model for which infographic, and what it costs.
- One article, five readers: a librarian, a cartographer, a historian, an explainer and a storyteller read the same piece Write the article first, then send five agent readers through it: a catalogue, an ontology and maps, the arc, two minutes, and a deck.